Total
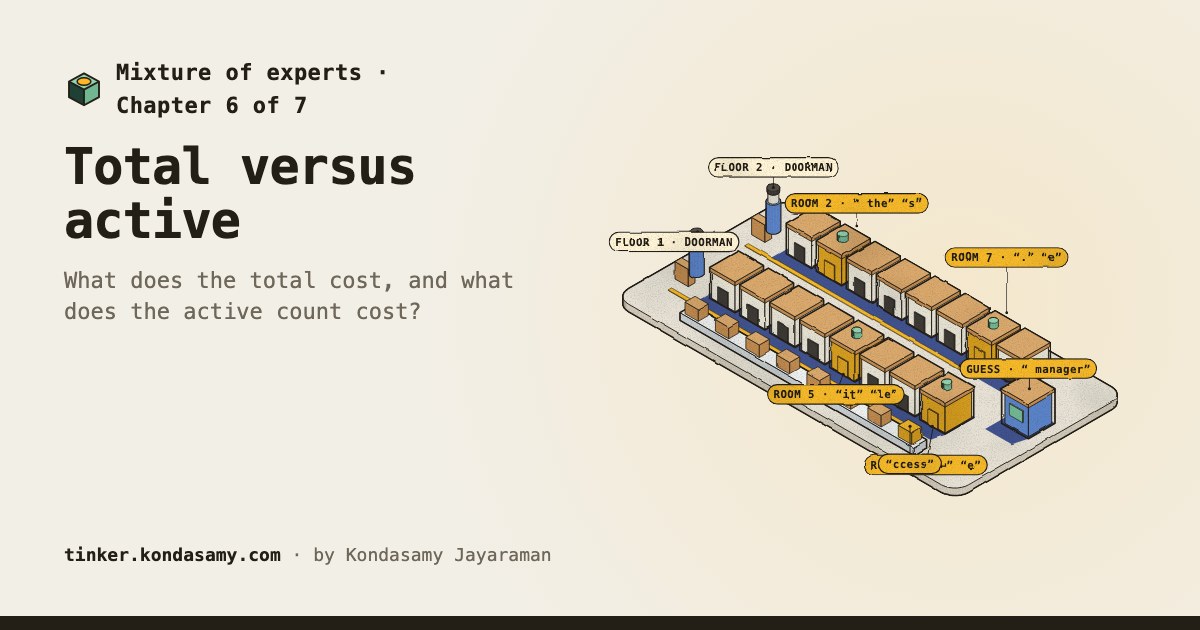
in memory46.7B
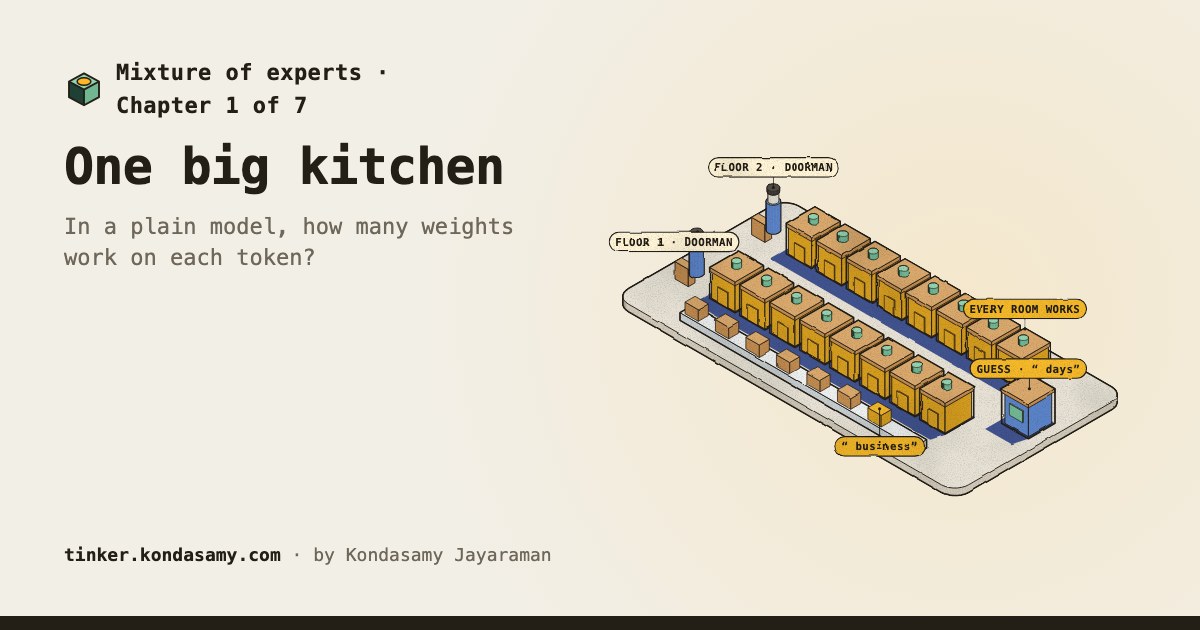
Every expert’s weights wait in memory, ready.
Module 39 · Mixture of experts
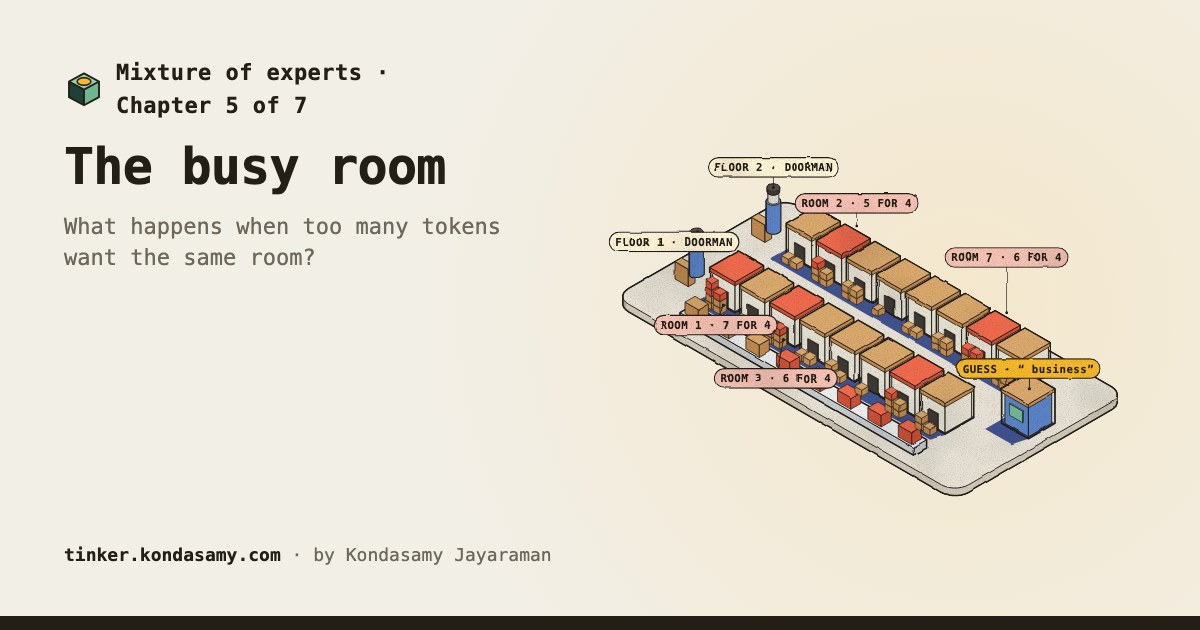
A mixture of experts holds many small networks but runs only a few for each token, picked by a router. Here you walk tokens through a sorting office, override its doormen, and size a model for Larkspur’s server.
The whole idea in one example
46.7B
Every expert’s weights wait in memory, ready.
12.9B
Each token runs through only its two chosen experts.
Mistral AI says Mixtral 8x7B has 46.7B total parameters but uses only 12.9B per token: 8 experts per layer, 2 chosen for each token. Source, checked 25 October 2026.
How it works
A dense model runs every weight on every token
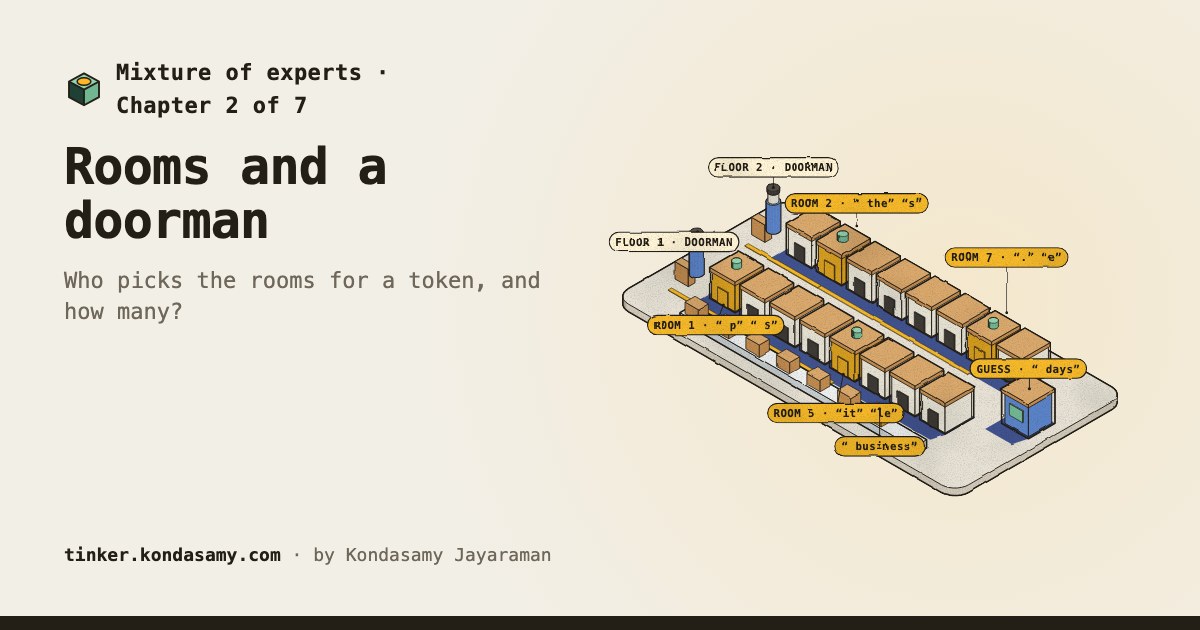
A router sends each token to two experts per layer
Shazeer and colleagues (2017) introduced the sparsely gated mixture-of-experts layer: a gating network picks a few experts per example, so capacity grows without the compute growing with it.
Source, checked 25 October 2026
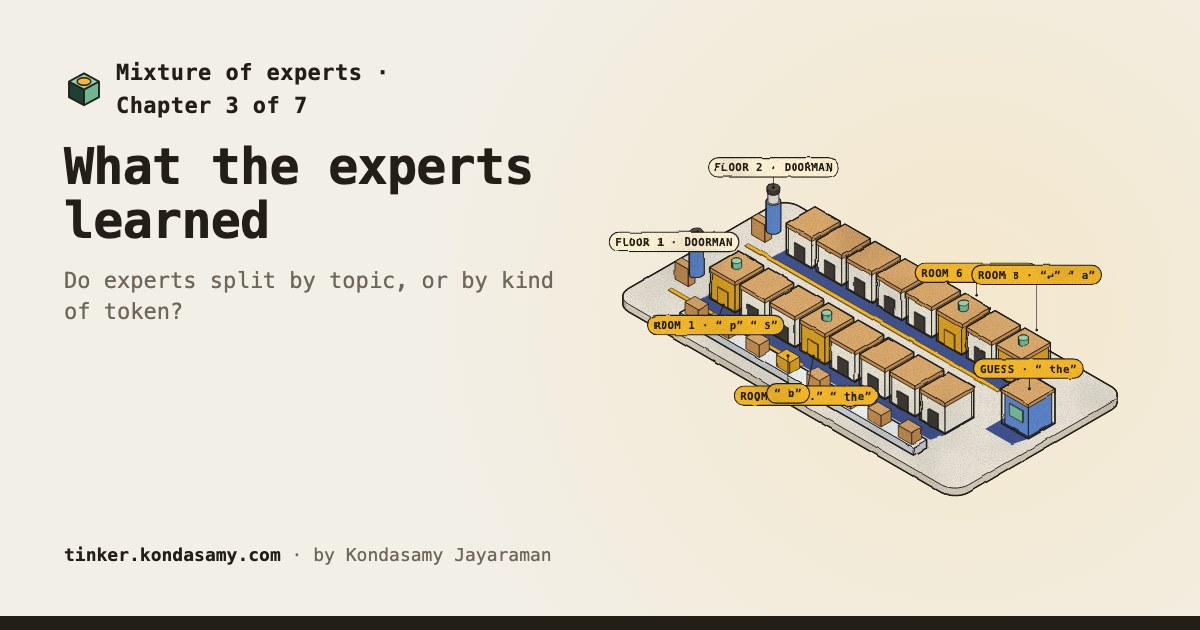
Other rooms do other work, so the guess changes
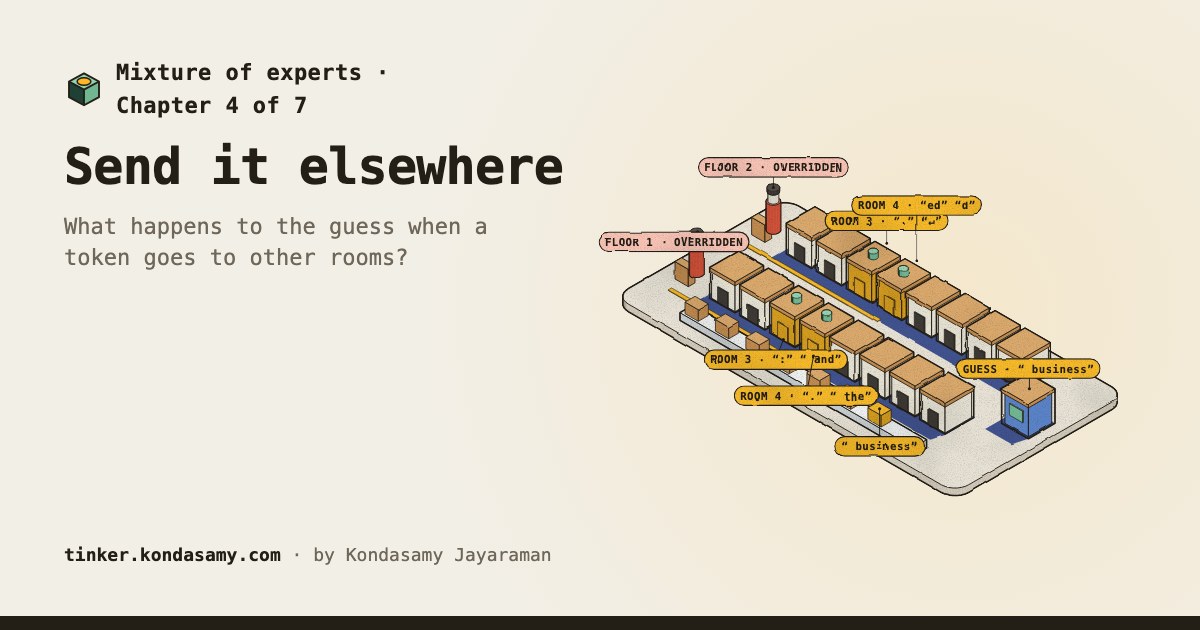
Full rooms turn tokens away
Switch Transformers (2021) give each expert a capacity of tokens per batch, set by a capacity factor; tokens past it are dropped and pass on through the residual connection.
Source, checked 25 October 2026
The story
A vendor’s model card says “47B total, 13B active”, and Larkspur Supply Co. wants to know what that means: the model holds many experts but pays for a few per word, and a router picks them. You’re on the team that picks the model.
Your path
Chapter 7 · done
Which model and precision fit both budgets with the most weights?
Anyone choosing between models whose cards quote a total and an active size, and who wants to know what each number costs. The Transformers module first helps, but no maths is needed.