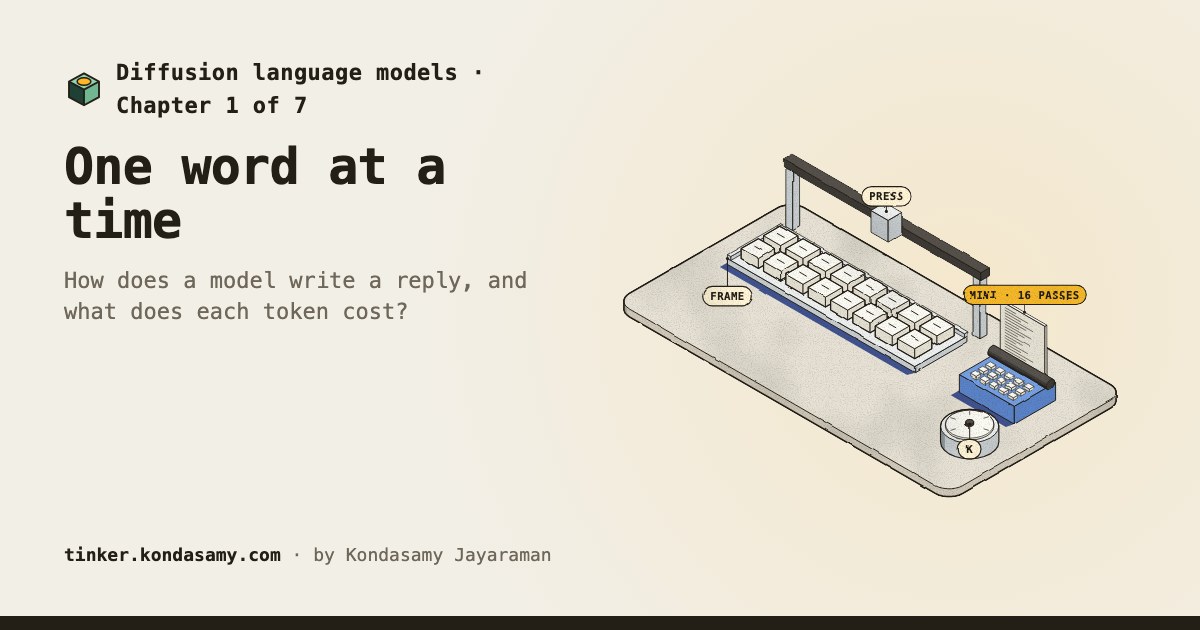
1 token a pass
16 passes“ years, to meet tax rules.↵↵Q: We place the sental sitted on the cand”
The careful fill: one token a pass, surest first.
Module 32 · Diffusion LMs
A diffusion language model starts from a reply of blanks and fills the surest first, several a pass. Here you run Larkspur’s toy masked model in a type frame, beside Larkspur mini’s typewriter, and see what fewer passes cost.
The whole idea in one example
“ years, to meet tax rules.↵↵Q: We place the sental sitted on the cand”
The careful fill: one token a pass, surest first.
“ years, to meet tax rules.↵↵Q: Wo the the a a a a a a the the thesee”
1 of 16 tokens the same as the careful fill; 9 repeats.
Both run Larkspur’s toy masked model, Larkspur mini’s size, trained once on Larkspur’s documents. It shows the mechanism; its replies are not what a production model writes.
How it works
A left-to-right model takes a pass per token
Larkspur mini continues “ safety boots and high-visibility” with “ reports.↵↵↵Q: Can I order? A: Yes”, one token a pass.
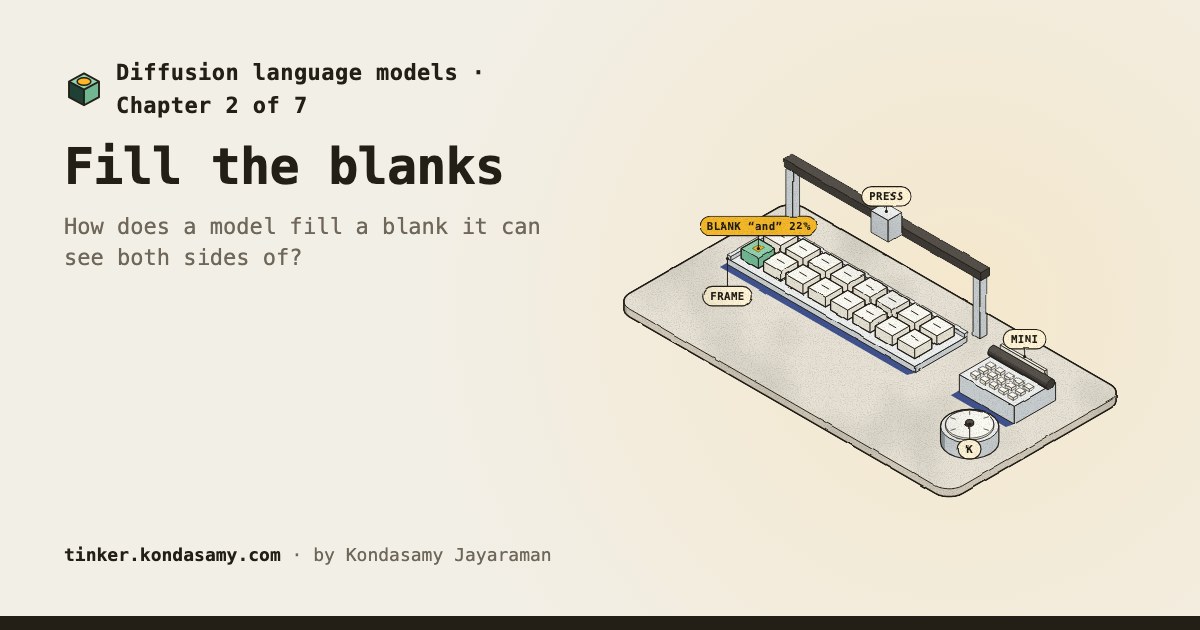
A masked model guesses every blank at once, reading both sides
MDLM (2024) found simple masked diffusion works better than previously thought, approaching left-to-right models’ perplexity, and can be sampled block by block for text of any length.
Source, checked 25 October 2026
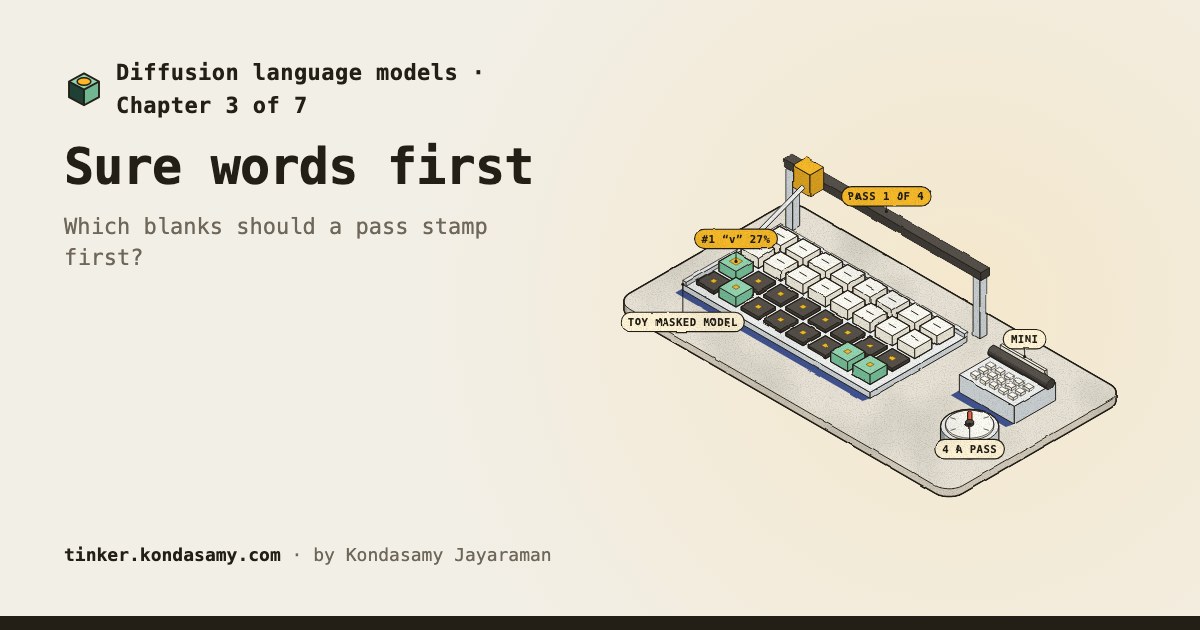
Each pass keeps its surest guesses
The LLaDA paper (2025), on an 8-billion-parameter masked diffusion language model, reports that low-confidence remasking (keeping the surest guesses) consistently outperforms random remasking.
Source, checked 25 October 2026
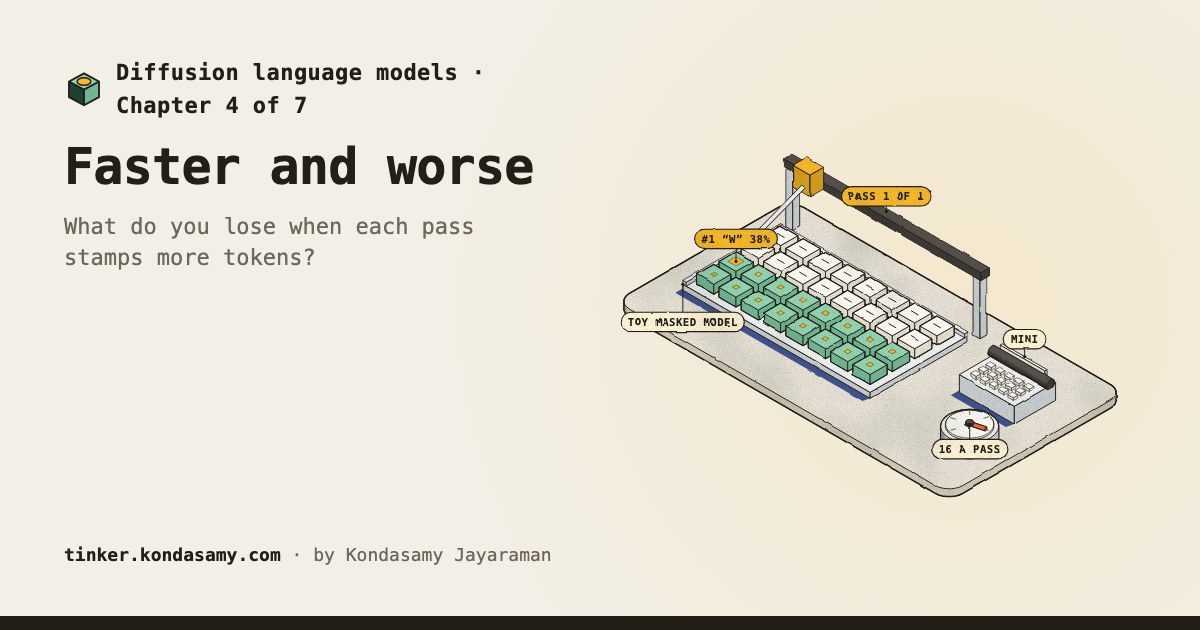
More tokens a pass: fewer passes, worse words
Fast-dLLM (2025) decodes only the tokens above a confidence threshold in parallel and adds an approximate key-value cache, reporting up to 27.6× more throughput with minimal accuracy loss.
Source, checked 25 October 2026
The frame’s size is set before the first pass
LLaDA sets the reply’s length before sampling starts: it begins from a fully masked sequence of that length, and drops whatever comes after the end-of-text token.
Source, checked 25 October 2026
Tokens a second = tokens a pass × passes a second
Inception, the vendor, claims its diffusion model Mercury 2 writes 1,009 tokens a second on NVIDIA Blackwell GPUs. The vendor’s own figure, from its blog.
Source, checked 25 October 2026
Everything here runs live in your browser: Larkspur mini, the left-to-right baseline, and the toy masked model, which fills the frame a pass at a time.
The story
A vendor promises a model that writes 1,009 tokens a second by filling a reply’s blanks in any order. Larkspur Supply Co. wants to know what that buys. You’re on the team that decides how many tokens a pass each kind of reply can take.
Diffusion models showed pictures coming out of noise, and Transformers showed a model writing left to right. Here text comes out of blanks.
Your path
Chapter 6 · done
What makes up tokens a second, and what should you ask about it?
Chapter 7 · done
How many tokens a pass, and which remasking, does each kind of reply need?
Product managers, engineers and analysts weighing a faster model. Diffusion models and Transformers come first; no code or maths needed.